Appearance
Knowledge base
Notes filed under 📖 DeepLearning Theories / Reinforcement Learning.
📖 DeepLearning Theories / Reinforcement Learning
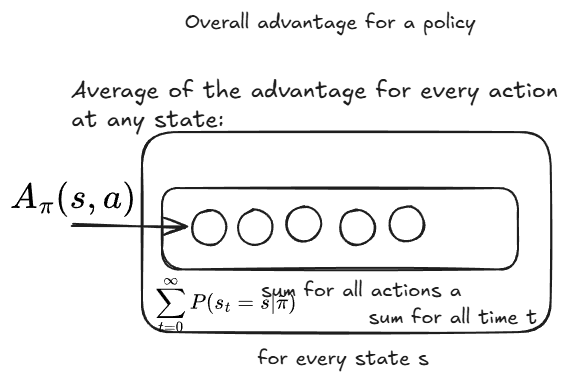
TRPO improves a policy monotonically by maximizing a surrogate advantage inside a trust region measured with KL divergence. Use it when policy-gradient updates must stay stable, and as the reference that later methods such as PPO simplify.